Free Your Team from PDF Overload. Reclaim 80% of Processing Time.
Astera ReportMiner automates the entire PDF workflow, from intake to ready-to-use data:
- Process scanned, long, and variable-layout PDFs with AI and OCR
- Extract, validate, clean, and transform data in a unified no-code workflow.
- Deliver clean data to Excel, databases, CRMs, and 300+ destinations
* Best suited for teams processing high volumes of complex PDFs.
See ReportMiner work on your documents
A live demo on real documents you bring. No slides, no scripts.
Trusted by 500+ Enterprise Users for PDF Processing
“ReportMiner converts long, complex purchase orders and PDFs into usable data in about two minutes. It handles complicated formats across every scenario we've encountered, giving us the speed and accuracy needed to automate the process.”
Hayder Mir, Sr. Manager, Custom Application
at Ciena Corporation
Want to see similar results with your PDFs?
Book a DemoGo Beyond PDF Extraction. Automate the Entire Workflow in One Place
Process PDFs from Any Source, in Any Condition
Skip the manual prep. Automatically ingest and process PDFs from email, folders, SFTP, and cloud storage, even when files are scanned, damaged, or thousands of pages long.
Keep Accuracy Consistent at Scale
Get reliable results from page one to page 10,000, so growing PDF volumes don't mean more manual review.
Built for High-Volume, Unattended Operation
Process thousands of PDF pages per hour with automated pipelines that run around the clock. Purpose-built for enterprise extraction workloads that can't afford downtime or manual intervention.
Easy-to-Use Interface Powered by AI
Build and automate PDF workflows with a visual, drag-and-drop interface. Preview results instantly and adjust logic using natural language, no coding or engineering support required.
Get Clean Data Before It Reaches Your Systems
Validate, standardize, and transform extracted data in the same pipeline. Fix formats, flag anomalies, and reshape fields so output lands ready to use, not ready to clean.
Handle Exceptions Without Stopping the Batch
Route documents that fail validation for review while the rest of the workload continues processing.
Automate PDF Processing on Files Other Tools Send to Manual Review
Invoices
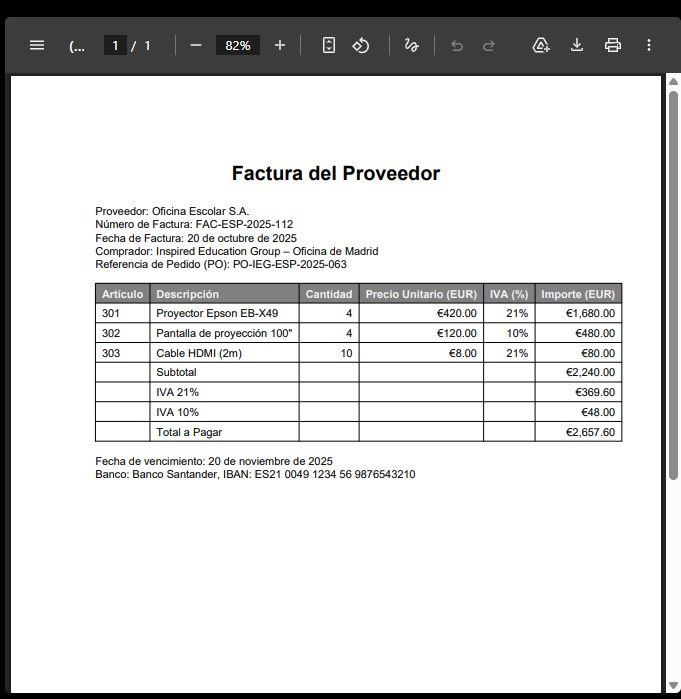 Source Document
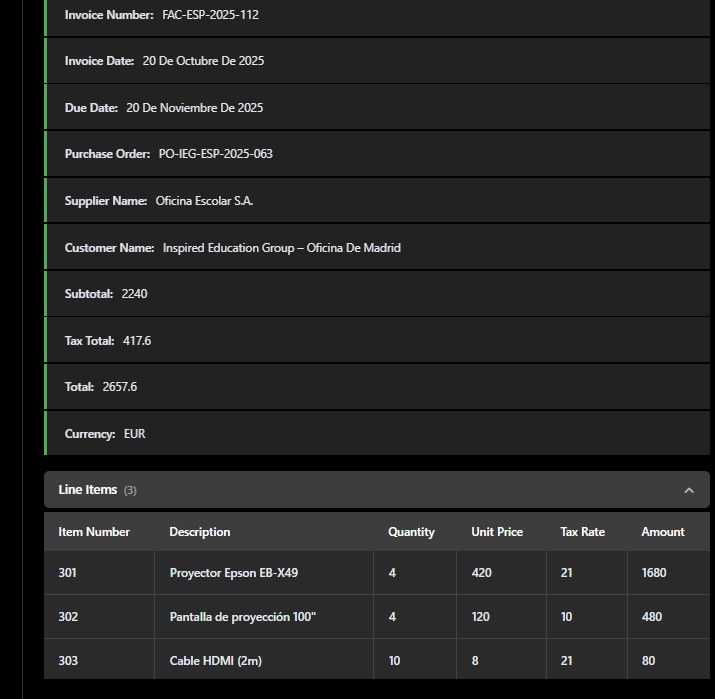 Extracted in ReportMiner
ReportMiner combines 15 years of template-based pattern matching with AI-powered extraction in a single platform. Use templates where precision matters, AI where flexibility matters, or both together. That is what the PDF processing software looks like in practice.
See how ReportMiner can cut manual PDF processing and deliver accurate, ready-to-use data faster.
Book a Demo


A PDF Processing Tool That Connects to Your Existing Stack
Astera ReportMiner can receive PDFs from your existing environment and deliver processed data directly to downstream applications.
File Systems
Web Services
Databases
Formats
Automate PDF Processing Without Sending Sensitive Data Outside Your Environment
Deploy ReportMiner on-premise, in a private cloud, or hybrid, and process sensitive PDFs without sending data outside your environment.
PDF Processing, Answered
What should I look for in a PDF processing tool for enterprise volumes?
Four things separate a PDF processing tool built for occasional use from one built for production. It needs automated intake rather than manual upload, consistent accuracy on long documents and large batches, exception handling that keeps a batch running when one file fails, and native delivery into your systems instead of a download step. ReportMiner covers all four in one pipeline, and runs on-premise when documents cannot leave your environment.
Can PDF processing software handle scanned and low-quality documents?
Yes. ReportMiner applies adaptive preprocessing, including skew correction, noise removal, and contrast adjustment, before OCR runs, which lets it process pages that are rotated, faded, watermarked, or handwritten. Post-OCR semantic correction then checks values against the document's own patterns to catch character misreads that OCR alone would miss.
How much volume can PDF automation software process?
ReportMiner processes thousands of pages an hour on automated pipelines, with no per-page fees, so cost stays flat as volume grows. One customer reports processing more than 40,000 PDF contracts in roughly four days, work that previously took weeks.
Does ReportMiner also merge, split, or compress PDF files?
No, and that is a useful distinction. ReportMiner is a data processing platform rather than a PDF editor. Its purpose is turning documents into structured data your systems can use, so if you need file manipulation utilities, a standard PDF editor is the better fit. If you need thousands of documents converted into validated records on a schedule, that is what ReportMiner is built for.
How long does it take to set up a PDF processing pipeline?
Most teams build a working pipeline for a document type in a single session, either by defining a template on a sample file or pointing AI extraction at a document with an irregular layout. From there the pipeline runs on a schedule, and adding a second document type reuses the same intake and delivery configuration.
Do non-technical users need IT to maintain a pipeline?
Not for routine changes. The visual interface and natural language copilots let operations teams add fields, adjust validation rules, and update logic when a vendor changes a layout. IT stays involved for deployment, access control, and system connections.
Put Your PDF Processing on Autopilot
Set the pipeline up once, connect it to your systems, and let ReportMiner collect, process, and deliver documents on schedule.