Enterprise PDF Data Extraction Software
Automate Data Extraction from High Volumes of PDF in a No-Code Tool
Astera ReportMiner automates PDF data extraction from invoices, reports, statements, contracts, scans, handwritten docs, and other files.
- Automatically processes scanned, long, and variable-layout PDFs with AI and OCR
- No-code platform to extract, clean, validate PDF data in an automated workflow
- Writes clean data to Excel, ERP, CRM, databases and 300+ destinations
Start a Trial
★★★★★
5/5
on Gartner Peer Insights
* Best suited for teams processing high volumes of PDFs.
Real Results from Real Customers
Trusted by 500+ Enterprise Users for PDF Data Extraction
Want to see similar results with your PDFs?
Book a DemoHow PDF Extraction Automation Works
From Raw PDF to Extracted Data in Your System. No Manual Handoffs.
1Step 1 of 6
Ingest PDFs From Any Channel
Pull PDFs from email, file drops, FTP/SFTP, cloud drives, web services, or API calls. ReportMiner accepts native, scanned PDFs, image-based PDFs, password-protected files, and multi-page documents. No preprocessing required.
2Step 2 of 6
Classify Each PDF by Layout
ReportMiner automatically identifies the document type and routes it to the right extraction template - invoices, statements, reports, contracts, forms - even when layouts vary by vendor or source.
3Step 3 of 6
Extract Structured Data Field by Field
AI-assisted field mapping plus character-position extraction pulls headers, line items, tables, and totals with field-level accuracy - across single-page invoices and 200-page reports alike.
4Step 4 of 6
Validate Before Anything Hits Your System
Built-in validation rules check totals, formats, required fields, and cross-document consistency. Flag anomalies, route exceptions for review, and only let clean records flow downstream.
5Step 5 of 6
Export to Wherever Your Data Lives
Push extracted data straight to SQL Server, Oracle, Snowflake, Salesforce, Dynamics, SAP, Redshift - or as CSV/JSON/XML - through 100+ native connectors. No middle layer, no manual export.
6Step 6 of 6
PDF Automation That Runs Unattended
Schedule your automated PDF processing pipelines to trigger on emails, file drops, time schedules, or API events. Distribute batch jobs across multiple servers for parallel processing. Once configured, your pipeline runs without manual intervention.
Why Astera ReportMiner
AI PDF Extractor Built for Enterprise Document Automation Workflows
Extract Data from Complex PDFs
Extract data from scanned, rotated, watermarked, handwritten, damaged, and thousand-page PDFs without manually fixing them first.
Get Consistently High Accuracy on Every Page
ReportMiner' OCR and AI Template-less technology holds the same accuracy whether you extract 10-page long PDF or run the same template across 10,000 pages.
Built for High-Volume, Unattended Operation
Automate extraction from thousands of pages an hour. ReportMiner runs automated PDF extraction pipelines around the clock without needed manual intervention or downtime. Best for enterprise document workloads.
Easy-to-Use Interface Powered by AI
Build and automate your entire PDF data extraction workflow through a no-code visual interface, preview results instantly, and adjust logic using natural language copilots.
Get Clean, Validated Output
Validate, standardize, and transform extracted data the moment pdf data capture software pulls it off the page. Fix formats, flag anomalies, and review output in the same pipeline.
Keep Sensitive PDFs Inside Your Environment
Deploy on-prem or in your private cloud so sensitive PDFs never leave your infrastructure. Best for regulated industries, government agencies, and enterprises with strict data residency requirements.
Free Your Team from Manual PDF Work
Turn complex PDFs into accurate, ready-to-use data that flows directly into your systems.
High-Volume Processing
Enterprise-Grade Security
Award-Winning Support
Book a Demo
Built for Complex PDF Data Extraction
Easily Extract Data from PDFs like Bills of Lading and Mainframe Report
Source Document
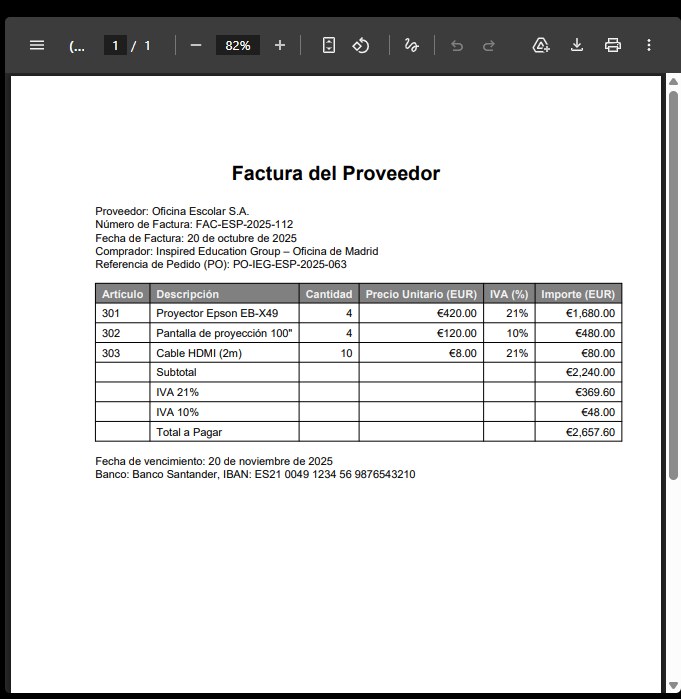
Extracted in ReportMiner
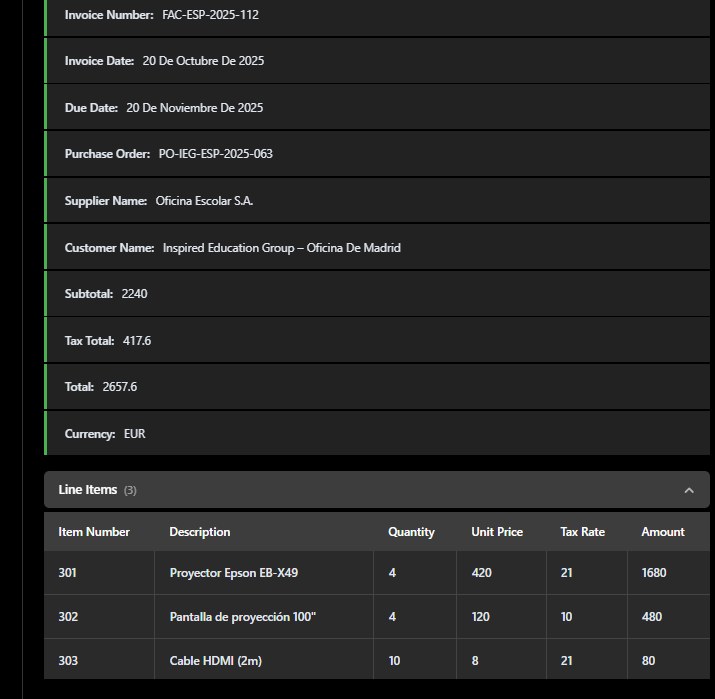
Template Precision + AI Flexibility = Reliable Extraction
for Every PDF
ReportMiner combines pdf table extraction, with pdf information extraction ai for documents that don't follow a fixed layout. Use templates where precision matters, AI where flexibility is needed, or both together in the same pipeline.
This is reliable PDF data extraction in practice.
Award-Winning AI PDF Extractor
Turn Complex PDFs Into Accurate, Ready-to-Use Data
See how ReportMiner can reduce manual extraction and turn your PDFs into accurate, ready-to-use data.
Book a DemoIntegrations
PDF Extraction Software That Connects to Everything
Astera ReportMiner fits into your existing infrastructure, ingesting PDFs from any source and delivering clean, structured data to any destination.
Storage and Transfer
FTP/SFTP
MFT
AWS S3
Azure Blob
SharePoint
Email (IMAP/STMP)
Web Services
REST APIs
SOAP
Webhooks
MCPs
Databases & Applications
SQL Server
Oracle
PostgreSQL
MySQL
Snowflake
Redshift
Salesforce
Dynamics CRM
and more via ODBC or APIs
Output Formats
Excel/XLSX
CSV
JSON
XML
TXT
Parquet
Common Questions
PDF Data Extraction, Answered
What's the best software to extract data from PDF files?
Astera ReportMiner is the best software to extract data from PDF files across scanned, digital-native, and mixed-format batches, using either template-based pattern matching or agentic extraction depending on how consistent the layout is. It exports directly to Excel, databases, or your ERP through 100+ connectors, so extracted data lands where your team already works.
Are pdf table extraction tools accurate on dense, multi-column layouts?
Most pdf table extraction tools lose accuracy past 15-20 columns or when tables include merged cells and multi-row headers. ReportMiner's template-based engine handles 50+ column layouts deterministically, with no hallucinated values and no column-shift errors, because it matches patterns rather than guessing at structure. For tables that change shape from page to page, the AI extraction mode adapts without a new template.
What is pdf information extraction, and how does it work in Astera ReportMiner?
Pdf information extraction is the process of pulling structured fields, tables, and line items out of a PDF and converting them into usable data. Astera ReportMiner does this through OCR for scanned pages, pattern matching for consistent layouts, and AI extraction for documents with no fixed structure. Extracted values pass through validation rules before export, so formatting errors get caught before the data reaches a database or spreadsheet.
How fast can I get data from PDF files with Astera ReportMiner?
Most teams get data from tens of PDF files within minutes of building a template or pointing the AI extractor at a sample document, then run the same pipeline unattended afterward. Astera ReportMiner processes thousands of pages per hour once a workflow is automated, with no per-page fees. Ciena Corporation cut purchase order processing from 30 minutes to under 2 minutes per document using this workflow.
Can I extract info from PDF files without writing code?
Yes. Astera ReportMiner's no-code visual interface lets you extract info from PDF files by defining fields, tables, and validation rules through point-and-click configuration. Natural language copilots can also adjust extraction logic when a layout changes, so non-technical users can maintain templates without involving IT for every update.
Can Astera ReportMiner extract content from PDF files that are scanned or low quality?
Absolutely. Astera ReportMiner has intelligent OCR that applies adaptive preprocessing, including skew correction, noise removal, and contrast adjustment, before running OCR, so it can extract content from PDF files that are rotated, faded, watermarked, or handwritten. Post-OCR semantic correction then checks extracted values against the document's own patterns to catch character misreads that OCR alone would miss.
Does ReportMiner use ai pdf extraction, or only fixed templates?
Astera ReportMiner supports both. Template-based extraction gives deterministic results on layouts that stay consistent, and ai pdf extraction handles documents with no fixed structure or documents that change layout from vendor to vendor. Both modes run in the same pipeline, so a single workflow can route structured invoices to a template and irregular ones to AI extraction automatically.
Get Started
Extract Every PDF Into Accurate Data That Moves Your Business Forward
Set up once, connect to your systems, and let Astera ReportMiner continuously extract and deliver structured data.
Book a Demo01Process PDFs of any length, layout, or scan quality
02Reduce processing costs with no per-page fees
03Set up quickly with expert onboarding support